ReINVenTA
Research and Innovation Network for Vision and Text Analysis of Multimodal Objects
ReINVenTA is a Minas Gerais-based research network in the computational semantic processing of multimodal objects. The network, funded by FAPEMIG (grant RED-000106/21) and CNPq (grant 420945/2022-9), has been gathering research projects dedicated to building and evaluating computational models for representing objects such as TV shows and pairings of static images and text. To this end, it has mobilized laboratories and research groups from UFJF, UFMG, UFU, PUC-MG, UFPB, Case Western Reserve University, and Universitat Leipzig, with expertise in Model Development for Natural Language Processing, Multimodal Artificial Intelligence, Knowledge Discovery, and Assistive Technologies. With this confluence of expertise and projects, the ReINVenTA network sought to achieve:
the expansion of the FrameNet model's coverage for Brazilian Portuguese;
the creation of a gold-standard dataset of semantically annotated and psycholinguistically validated multimodal objects;
the development of artificial intelligence algorithms for automatic labeling and knowledge discovery in multimodal objects;
the proposal of best practices for video audio description.
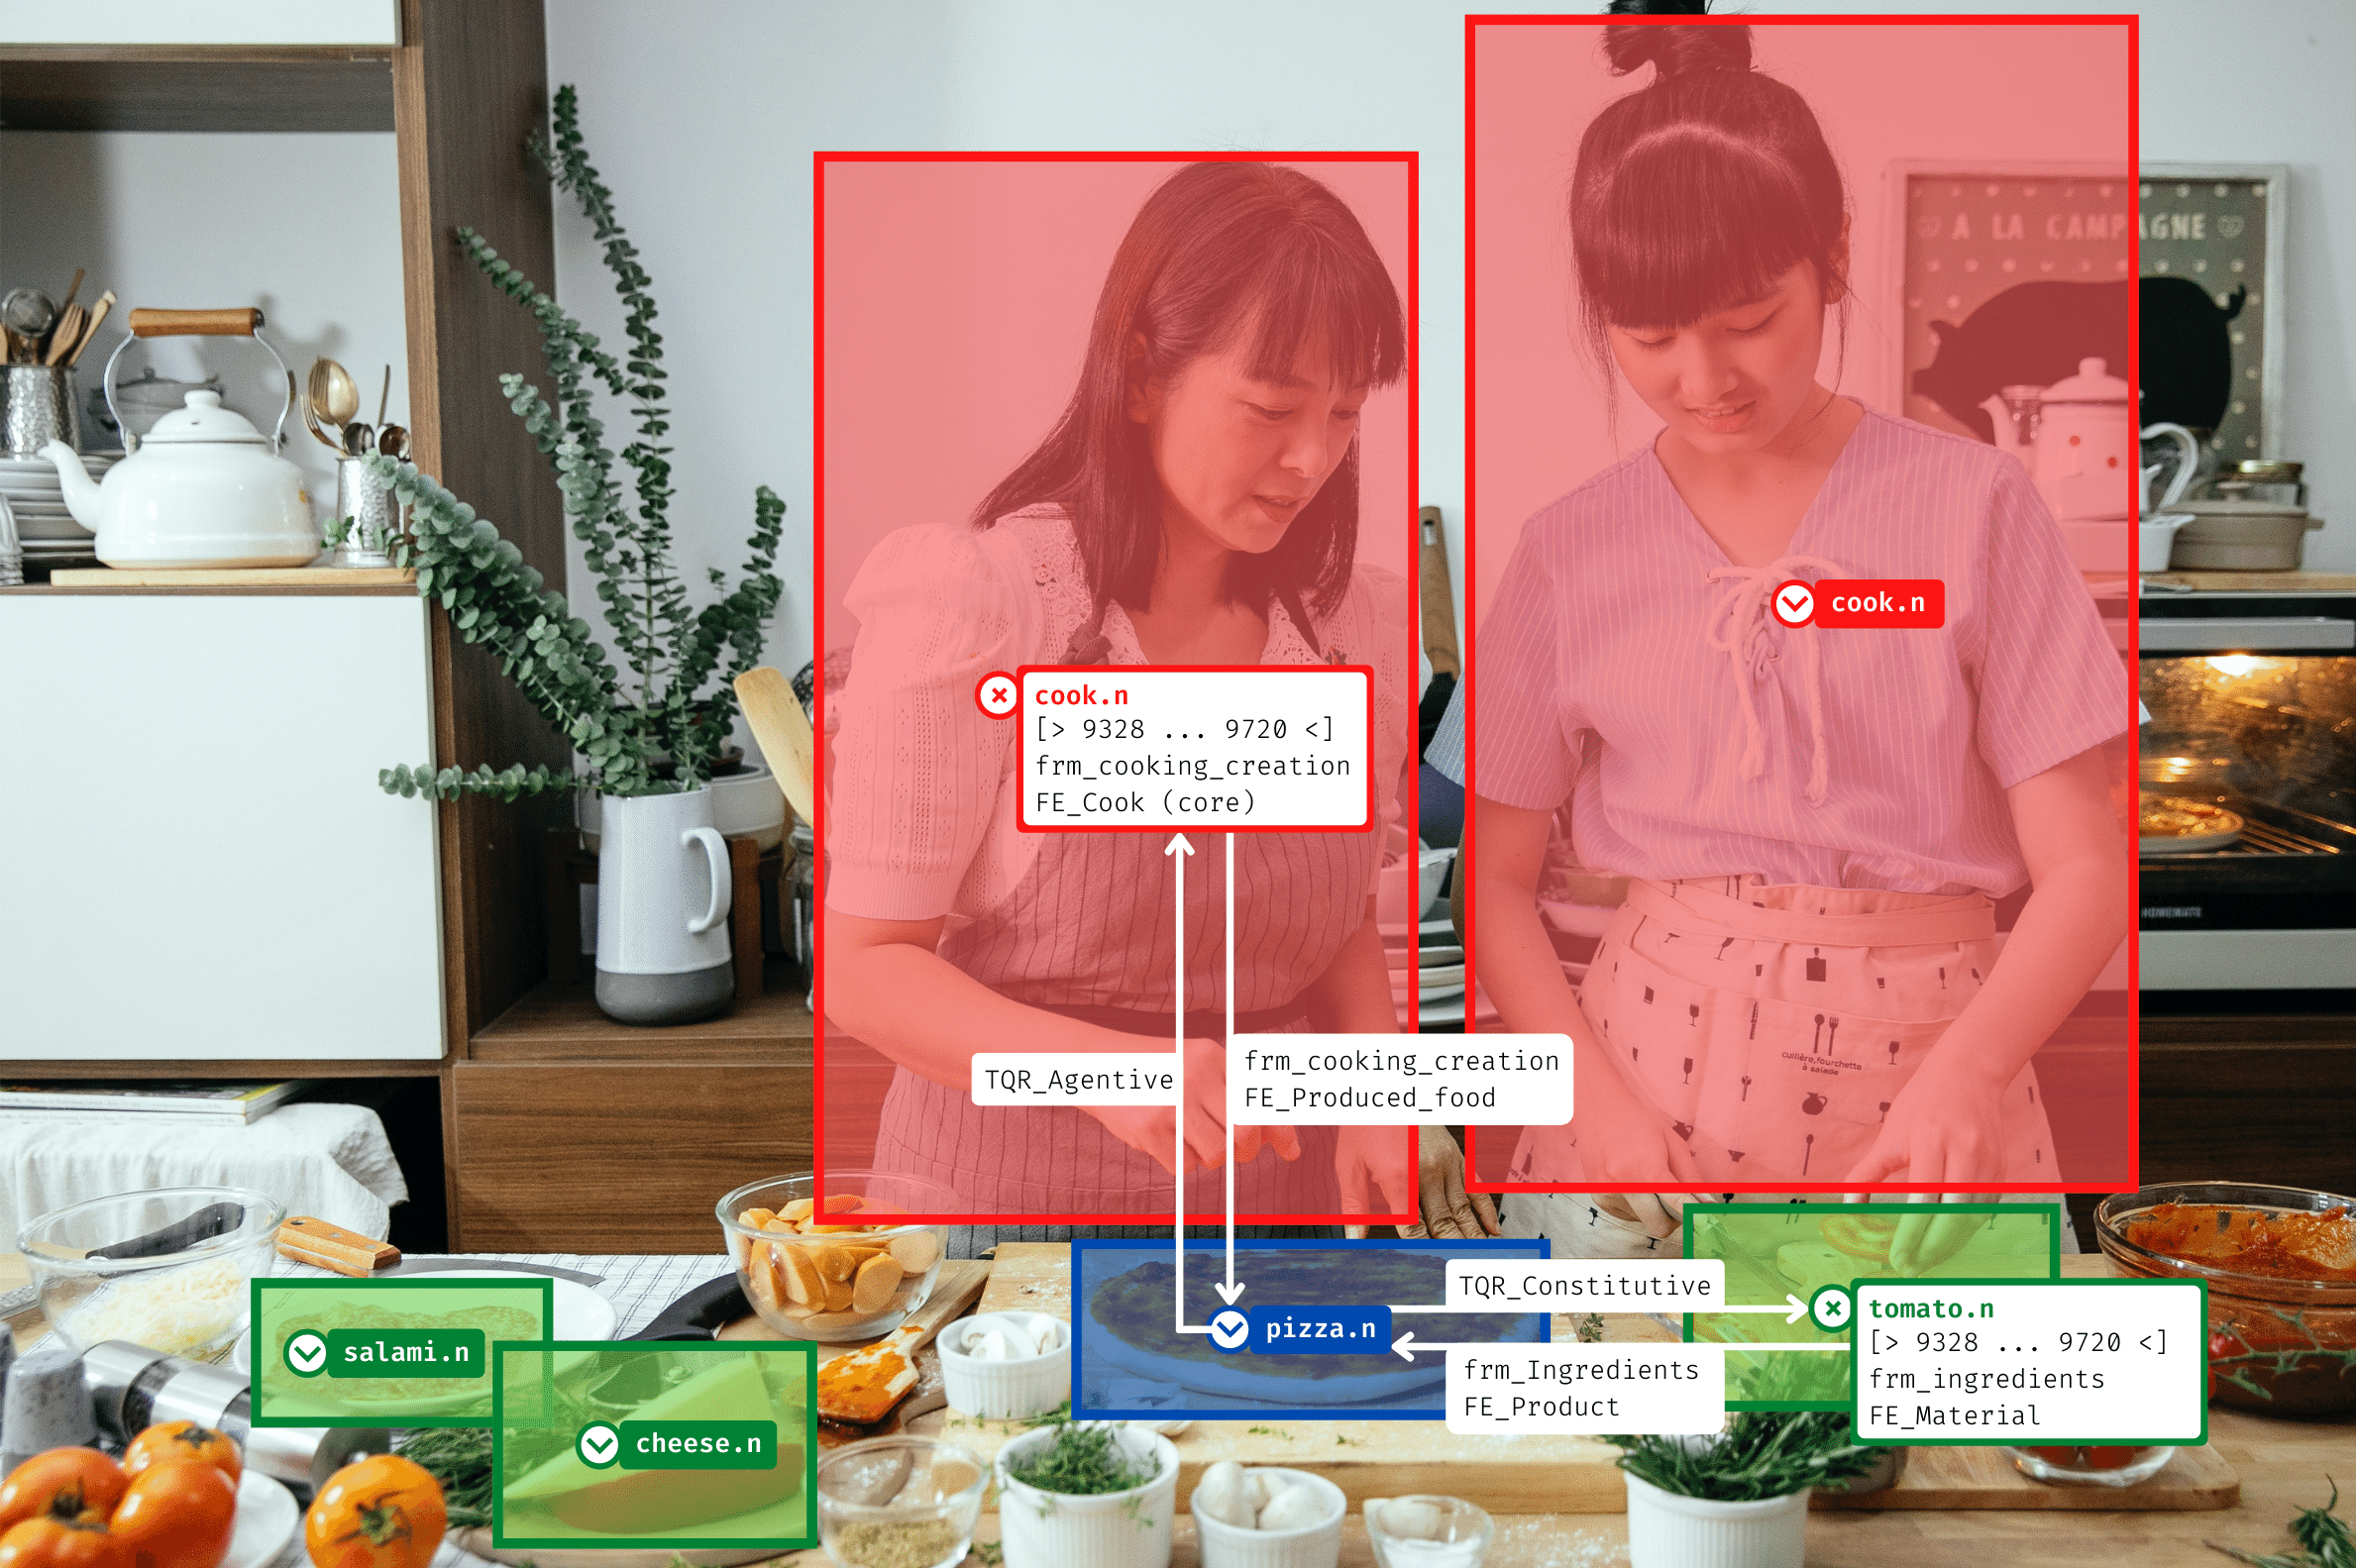
What is the nature of the produced dataset? For AI models to achieve semantic precision, the existence of human-curated datasets is indispensable. ReINVenTA has developed a database that aligns bounding boxes and verbal texts annotated for semantic frames, allowing machines to "understand" complex scenes and not just identify isolated objects.
The constitution of the ReINVenTA dataset is characterized by the integration of four specific subsets of gold-standard multimodal data: Framed Multi30K, Frame², Audition, and FramedNews, all made freely available for non-commercial use under a CC 4.0-NC-BY license.